ProjectClassic ML
Automated document extraction feeding a prediction model
Automated intake of PDFs and machine logs into a prediction model, with OCR, ETL and monthly retraining, replacing manual work.
Stack
- S3
- DynamoDB
- Textract
- Lambda
- ECR
- EventBridge
- CloudWatch
- X-Ray
- +7
01 · How it works
- TodaytoChanged in this work
- Data flow
What it does
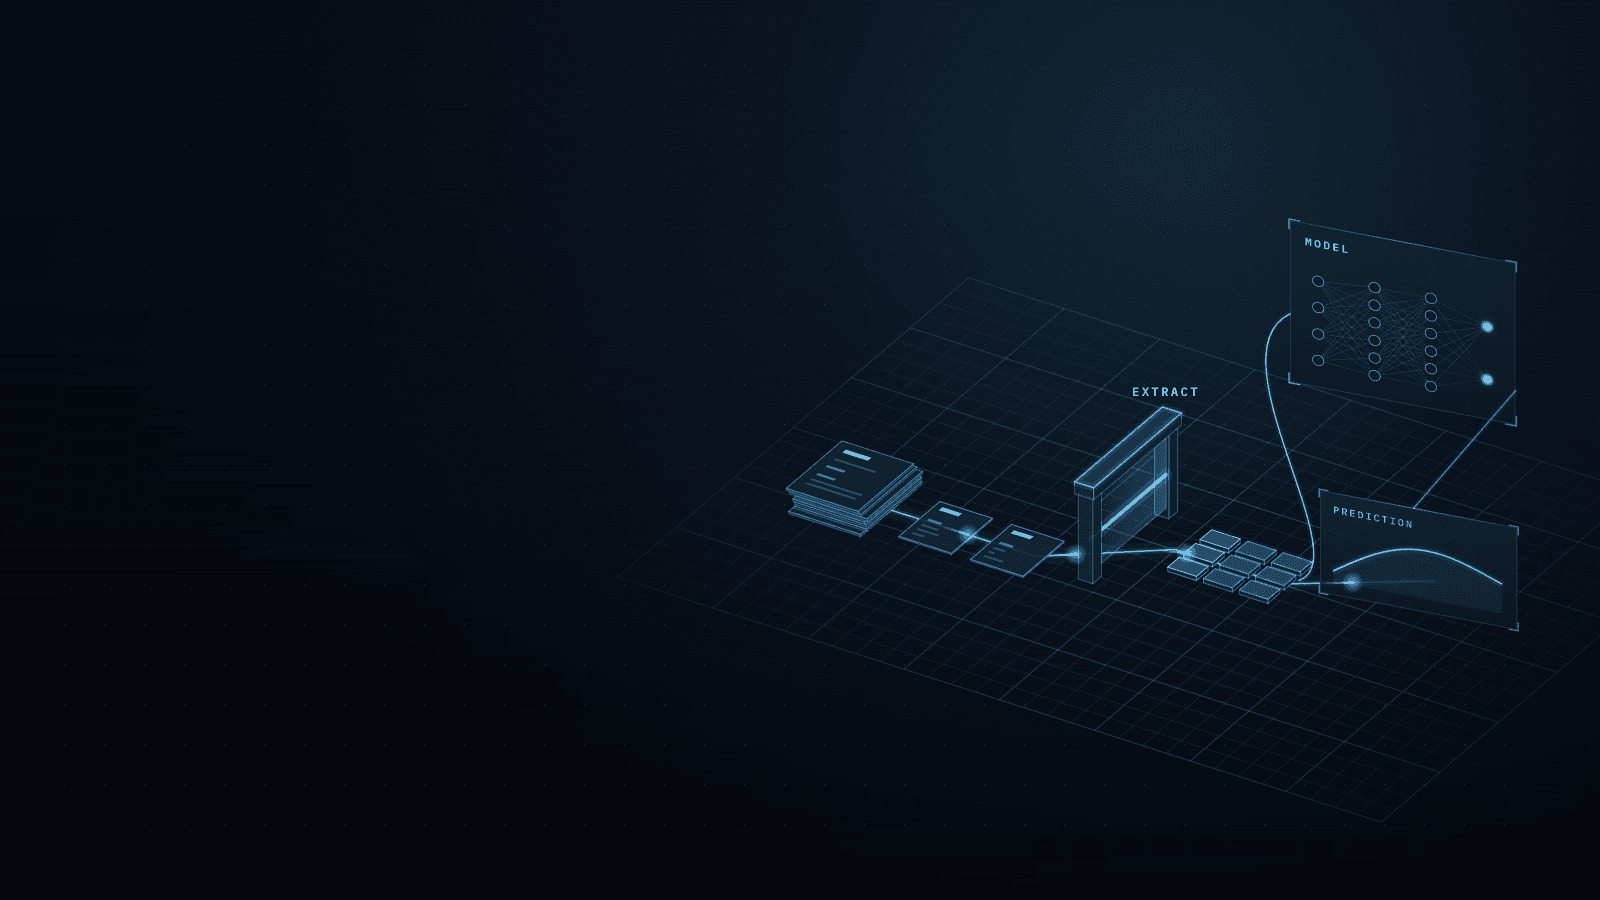
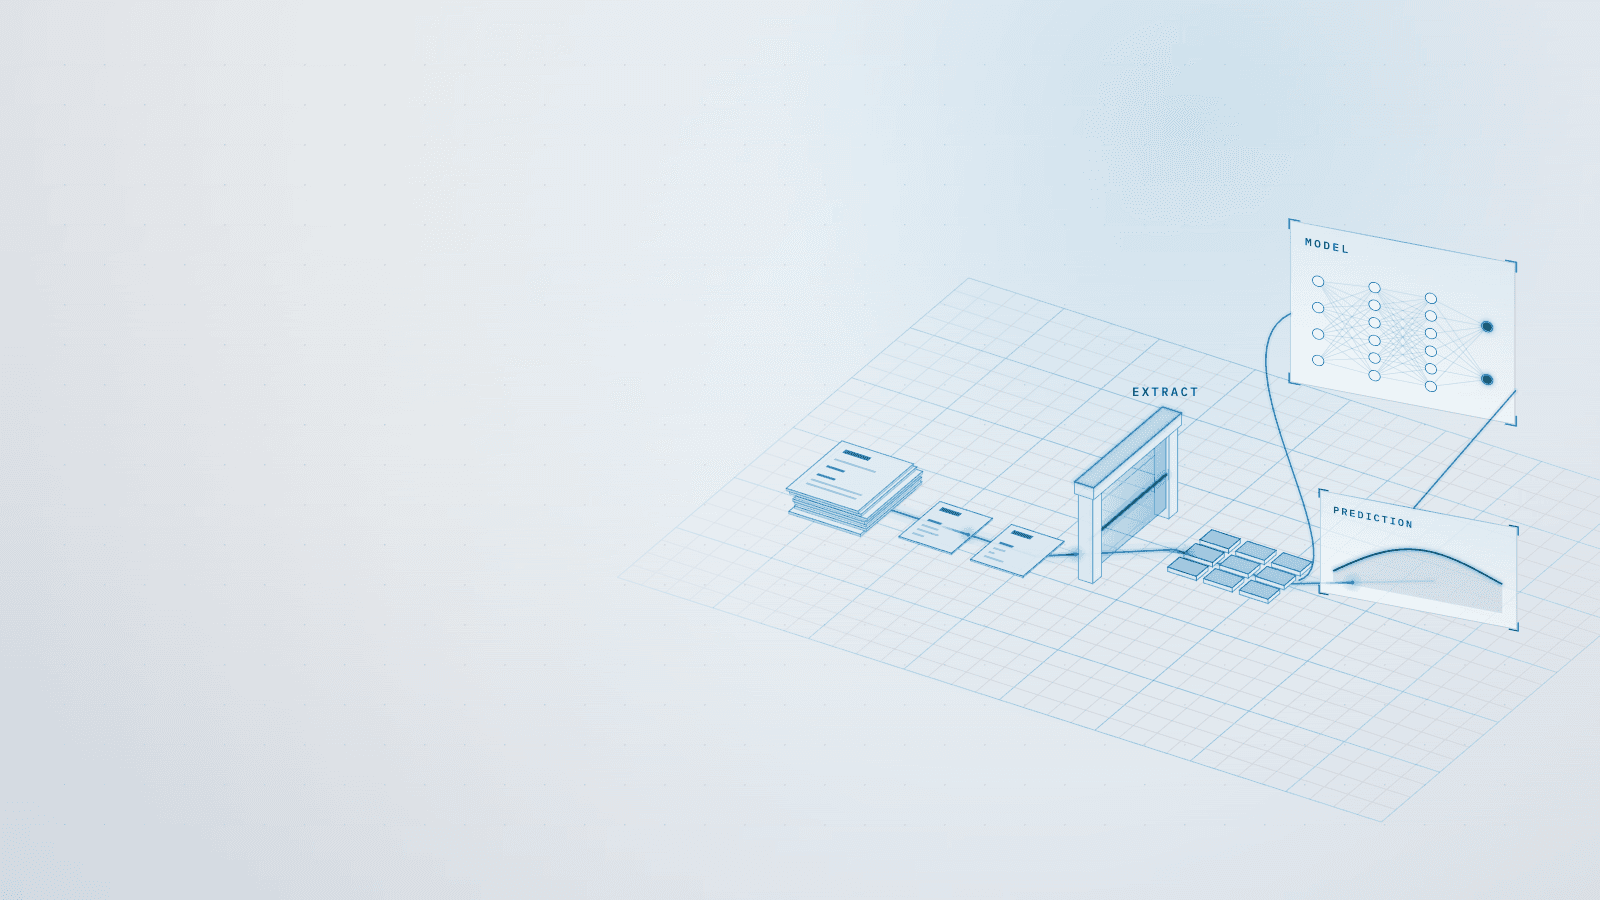
An event-driven platform that takes PDF documents and machine log files from upload to prediction without manual handling. A web client queues each job; serverless functions route documents to managed OCR, ETL pipelines clean and join the extracted data with the logs, and a containerised model serves predictions.
Read more
I designed it as an end-to-end data engineering and MLOps system, including monthly retraining that promotes the best model to the prediction API.
6 connections· select a part to trace it
- Web client to Job queue: job orders
- Job queue to PDF router function: S3 upload event
- PDF router function to Managed OCR service: laser-generated PDFschanged
- Managed OCR service to ETL pipelines: raw text via data lake
- Machine log files to ETL pipelines: machine logs
- ETL pipelines to Model, retrained monthly: clean feature tables
02What it achieved
Outcome
- Intake: a manual, error-prone workflow → automated from upload to prediction
- Data quality: PDFs and machine logs cleaned and joined consistently by two ETL pipelines
Read more
- Model lifecycle: monthly retraining, with the best model promoted to the prediction API
- Operability: three event-driven functions traced and monitored end to end
The challenge
The inputs were inconsistent by nature: PDFs from different sources needed different handling, and machine logs had their own formats and noise. A router function inspects each incoming document and sends the laser-generated ones through managed OCR, and the raw extraction lands in a data lake before any transformation, so every step can be rerun and checked.
Read more
A model in production also drifts, so the system needed a training cycle of its own instead of a one-off model: scheduled retraining on fresh data, with the best model promoted automatically. With many functions involved, tracing and monitoring across the whole flow were part of the design, not an afterthought.
What I learned
Building the model was the smaller part; the platform around it is what made it useful. Routing documents by type before OCR, landing raw data before transforming it, and keeping the ETL separate from prediction made each stage testable on its own.
Read more
Treating training as a scheduled, automated job turned the model into something that can be maintained in production instead of a one-off result. Tracing across functions is what makes an event-driven system debuggable.
Stack
- S3
- DynamoDB
- Textract
- Lambda
- ECR
- EventBridge
- CloudWatch
- X-Ray
- API Gateway
- React
- Docker
- Python
- ETL
- JavaScript
- scikit-learn
Skills
- Event-driven architecture
- MLOps
- Document processing and OCR
- ETL design
- Serverless operations